 MIT News - Artificial intelligence0 followersVerified
Stay connected and personalize your Newswire experience.
How to predict the behavior of molecules from scant data
- Publisher
- MIT News - Artificial intelligence
- Topic
- Research
- Location
- Massachusetts, US
- Published
- Nov 6, 2026 · 7:00 PM
Las Vegas Newswire preserves the publisher's attribution and original-source link while adding publisher, topic and related-coverage navigation for readers.
Discovering new molecules for specific uses is a major driver of progress in a wide variety of industries, whether it’s pharmaceutical companies looking for new drugs, or electronics or energy companies seeking new materials with particular properties. But it’s also largely a trial-and-error process, because there is not yet any way to perfectly predict how a given chemical compound will behave in terms of the myriad different properties and responses materials can exhibit.
Recent progress has been made on using artificial intelligence and machine learning to supplement or speed up laborious calculations based on physical principles that can at least provide some initial guidance on which compounds might be worth synthesizing and testing. Now, a new method developed at MIT shows that when there are few data on some technologically relevant property, such as ligand affinities for a recently discovered cellular target for a potential drug, this approach can outperform other existing methods for winnowing down the field of possible molecules that might be worth looking at.
The findings were reported in the Sept. 14 issue of the Journal of Chemical Information and Modeling, in a paper by MIT graduate student Akshat Shirish Zalte and recent graduate Jackson Burns PhD ’26, Research Scientist Charlles Abreu, Professor William Green, and three researchers from the chemical company BASF.
An earlier version of the paper has been online since last year, and the open-source model the team developed, called CheMeleon, has already found regular use by several pharmaceutical companies. CheMeleon was built using ChemProp, an open-source machine-learning package also developed and maintained by the Green group at MIT, and anyone can download CheMeleon through ChemProp and fine-tune it for their own purposes.
Earlier this year, there was a contest organized by OpenADMET for trying to predict the properties of a variety of new molecules that had not previously been synthesized, says Green, who is the Hoyt Hottel Professor of Chemical Engineering. “It was a big contest, a lot of people participated,” he says. When the winners were announced, it turned out that nine of the top 20 entries had used CheMeleon in their process. “So then we started getting all kinds of inquiries from the pharma companies about this, but our paper had just been submitted; it wasn’t even peer-reviewed or anything yet.”
While the paper went through that review process, its influence was already spreading. At least one pharma company, Green says, “sent a message to all their people, and said ‘Anytime you’re modeling a property, start with CheMeleon, that’s our new company policy’” when making initial decisions about which molecules to pursue.
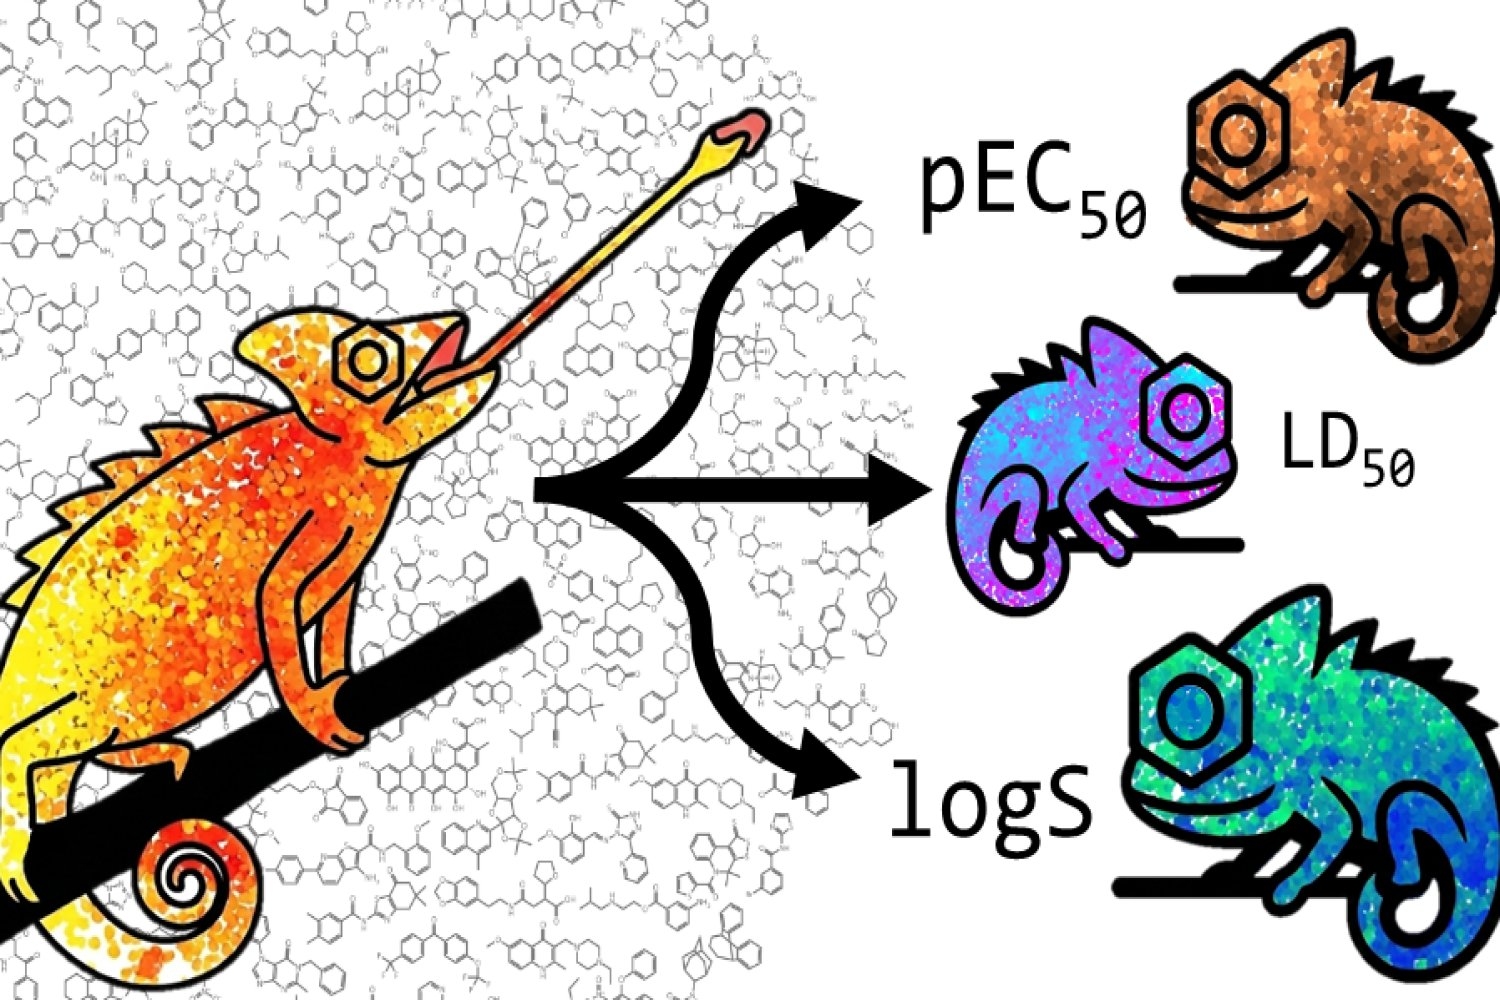
The key to CheMeleon was pre-training a machine-learning model with detailed data about a million different molecules, so that it gets to learn correlations between the structure of a given molecule and how it behaves with respect to a catalog of about 1,600 descriptors that have been developed by chemists over decades. CheMeleon can then be fine-tuned to predict well-known properties like solubility and viscosity, to more esoteric properties such as bioactivity or reactivity, with a certain protein or enzyme.
Those million molecules are a minuscule fraction of the innumerable ways that atoms can bond together, but they provide enough examples so that once the AI system has been trained on them, it can work out on its own many underlying patterns and relationships, and then apply those to a new, unknown molecule that’s presented to it.
“Most of today’s deep-learning models require more data than traditional methods,” says Zalte. Some successful models use extensive data from the published literature in chemical journals, he says. “We don’t look at the literature at all. We just calculate a bunch of molecular descriptors like molecular weight or number of oxygens, among others.” Then predicting those descriptors forms the basis for their pre-training task.
CheMeleon is a pre-trained foundation model. Inspired by the well-known foundation models in language such as ChatGPT and Claide, which essentially are developed by feeding them massive amounts of information from the internet, CheMeleon uses molecular descriptors of a million molecules from PubChem, a large, freely available database of chemical information maintained by the U.S. National Institutes of Health.
With classical expert-driven models, on the other hand, specialists in a field manually input detailed knowledge about their subject. In developing these classical models, he says, for example, people know from experiments that a certain property of interest, say solubility, may relate to particular descriptors of the same molecules, “like molecular weight, or the number of oxygens that are present, or how branchy or bulky the molecule is.”
With this team’s approach, they can start with an existing neural network architecture and train it to learn underlying principles. “We’re not training it for a specific property, but as a general model that understands some level of chemistry, so that even if you fine-tune it with just a few data points for the task you care about, you can still get some good performance,” he says. That’s thanks to the fact that the model is “not having to learn everything from scratch.”
To verify its usefulness, “We compared our model not only against other foundation models that are out there, but also with classical models leveraging expert-designed principles,” Zalte says. Comparing its performance across 58 test cases, “we see that our model comes out on top.”
Green adds, “The CheMeleon foundation model drastically reduces the number of molecules that need to be tested experimentally to accurately predict the properties of new molecules. This is a huge advantage, since synthesizing and testing a large number of molecules is slow and expensive."
Besides the MIT members, the team also included Jochen Sieg, Christian Feldmann, and Miriam Mathea, researchers at BASF SE in Germany. The work was supported by the Machine Learning for Pharmaceutical Discovery and Synthesis consortium, along with fellowship support from U.S. Department of Energy and MathWorks.
Article at a Glance
- Publisher
- MIT News - Artificial intelligence
- Author
- David L. Chandler | Department of Chemical Engineering
- Primary topic
- Research
- Coverage
- Massachusetts, US
- Published
- Nov 6, 2026 · 7:00 PM
About the Publisher
MIT news feed about: Artificial intelligence
View MIT News - Artificial intelligence on the Publisher Network
Coverage
This report is associated with Massachusetts, US based on the location metadata supplied with the story or publisher profile.
Topics & Keywords
Primary topic: Research
Related topics: Research, Massachusetts, Technology
Frequently Asked Questions
Who published this report?
This report was published by MIT News - Artificial intelligence and credits David L. Chandler | Department of Chemical Engineering as the author.
What is the primary topic?
The story is categorized as Research in the Newswire metadata.
What area does this story cover?
The available Newswire metadata associates this report with Massachusetts, US.
What do you think about this story?
Share your perspective and join the conversation with other readers.
Discussion is hosted by Las Vegas Newswire. Publisher attribution and the originating report remain unchanged.
About Las Vegas News Publisher Network
Las Vegas News Publisher Network is the publisher-distribution network operated by Las Vegas News. It organizes reporting from participating publishers while preserving publisher attribution and links to the original source.
MIT News - Artificial intelligence0 followersVerified Stay connected and personalize your Newswire experience.
Loading recommendations…